Showing posts with label Apache. Show all posts

Run Apache NiFi Docker on Mac M1

In my recent articles on Apache NiFi, I explained how to run Apache NiFi on Docker and Docker Compose. Recently I got a Mac Book M1 Pro machine from work and surprisingly I couldn't run Apache NiFi on Docker in Mac Book M1. Though the Apache NiFi binary deployment works fine on Mac M1 architecture, the official Apache NiFi Docker image does not support Mac M1 yet (at the time of writing this article). However, Chris Sampson a NiFi committer provided a script to build NiFI docker image that is compatible with Mac M1. This article explains, how to build Apache NiFi docker image on your Mac Book M1 and how to run it.

Disclaimer: Since this is not an official image, I recommend this method only for pipeline development and testing purposes.

Run Apache NiFi in Docker with SSL Enabled
Read More

Run Apache NiFi Cluster in Docker with SSL Enabled

Welcome to the fourth article in the series of Apache NiFi. The last article explained how to set up an Apache NiFi Docker container with a self-signed SSLcertificate. This article addresses the next pain point: how to create an Apache NiFi cluster in Docker with SSL enabled. Unlike HTTP cluster, setting up Apache NiFi cluster with SSL enabled in Docker introduces a new challenge: Hostname verification.

For added security, if HTTPS connection is enabled, Apache NiFi will verify the Hostname of requests. Therefore each request sent to Apache NiFi must have a predefined hostname. Not only the external requests, but peer-to-peer communication of NiFi nodes in a cluster also go through HTTPS and are subject to hostname verification. If the hostname provided in the HTTPS request does not match the hostname defined in the SSL certificate, NiFi will throw a javax.net.ssl.SSLPeerUnverifiedException.
Run Apache NiFi in Docker with SSL Enabled
If you are traditionally deploying Apache NiFi: individual servers with known IP addresses, it is easy to create certificates with those IP addresses. However, in a dynamic environment like Docker, the hostname of a container is defined at the runtime if you need flexible scaling options. Since Docker doesn't provide an option to define the hostname pattern in a scalable cluster, we have to stick to hard-coded Apache NiFi containers with predefined hostnames to create a cluster. The disadvantage of this method is that it is hard to scale up/down a cluster with hard-coded containers. Instead, you can also set up an HTTP cluster and create a load balancer with HTTPS frontend and SSL Termination between the client and NiFi UI. However, in this article, we will stick to the SSL configuration at the cluster level.
Read More

Run Apache NiFi in Docker with SSL Enabled

The last two articles in the Apache NiFi series discussed how to run Apache NiFi standalone server and NiFi cluster in Docker. However, those are far from production-ready because they are not secured. The next step in setting up a secured NiFi cluster is spinning up an Apache NiFi instance with SSL enabled in Docker. Though we are moving towards production-ready, this article will use self-signed certificates. In production, you should not use a self-signed certificate. In addition, you may also require additional safety measures like firewall and proxy.
Run Apache NiFi in Docker with SSL Enabled
Read More

Run Apache NiFi Cluster in Docker

The last article on Apache NiFi: Run Apache NiFi in Docker was for those who want to start playing with Apache NiFi. Though it was a good start to play with NiFi, it is far from production deployment. This article introduces the second stage of deployment: a NiFi cluster running in Docker using Docker Compose.

Run Apache NiFi in Docker

To begin with, you must have Docker installed in your system and also install Docker Compose as we are going to use Docker Compose to setup the Apache NiFi cluster. 

Read More

Log4J 2.17.0 is Vulnerable to RCE. Upgrade to 2.17.1

I know the wish list of all Java developers for Santa starts with "No more Log4J vulnerabilities". However sometimes even Santa cannot fulfill all your wishes. A new security vulnerability was found in Log4J 2.0-alpha7 to 2.17.0 excluding 2.3.2 and 2.12.4.

The new vulnerability allows Remote Code Execution (RCE) attack where an attacker with permission to modify the logging configuration file can construct a malicious configuration using a JDBC Appender with a data source referencing a JNDI URI which can execute remote code.

Log4J 2.17.0 is Vulnerable to RCE. Upgrade to 2.17.1

Unlike the CVE-2021-44228 that triggered the domino effect of Log4J vulnerabilities, CVE-2021-44832 is marked as a moderated risk since it requires access to your Log4J configuration. For those who don't know, projects using Log4J with the CVE-2021-44228 vulnerability can be exploited by submitting modified HTTP requests. On the other hand, CVE-2021-44832 requires direct access to the Log4J configuration for an outsider. If somebody got the access to your system to modify the Log4J configuration, you are already doomed. Therefore, you may not need to rush to apply the patch if your system is already secure enough.

Similar to CVE-2021-44228 and CVE-2021-45105, CVE-2021-44832 also affects log4j-core only.

The CVE-2021-44832 issue particularly hasn't affect Log4J 1.x versions. However, Log4J 1.x is not maintained anymore and do not expect any security patches in case if a security vulnerability is found in the future. Based on Java versions, upgrade to the latest version with the fix for all known security vulnerabilities so far.

Java VersionLatest Log4J Version
Java 8 and laterLog4j 2.17.1
Java 7Log4j 2.12.4
Java 6Log4j 2.3.2


The latest Log4J versions in the above table have fixed the issue by limiting JNDI data source names to the java protocol.

Let me repeat the process for developers to identify the vulnerable Log4J versions.

Run the following command from your project folder.

mvn dependency:tree

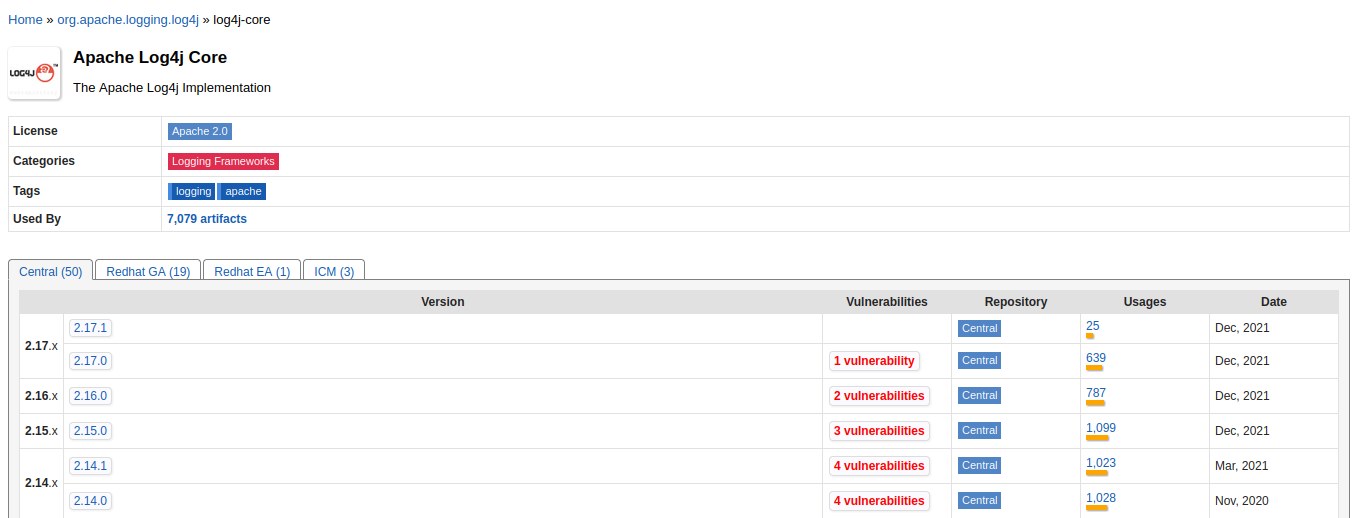
Any Log4J dependency with a version less than 2.17.1 is most likely vulnerable or unmaintained. Maven central repository has a new column with the number of vulnerabilities in each Log4j version.

Log4J 2.17.0 is Vulnerable to RCE. Upgrade to 2.17.1

If you encounter any vulnerable Log4j versions as your direct dependencies defined in your pom file, or in your parent pom file, upgrade them immediately. Remember by defining the following dependency in your pom file, you can override the dependency defined in your parent pom file.

<dependency>
    <groupId>org.apache.logging.log4j</groupId>
    <artifactId>log4j-core</artifactId>
    <version>2.17.1</version>
</dependency>


Log4J 2.17.0 is Vulnerable to RCE. Upgrade to 2.17.1 
Image Credits: Google

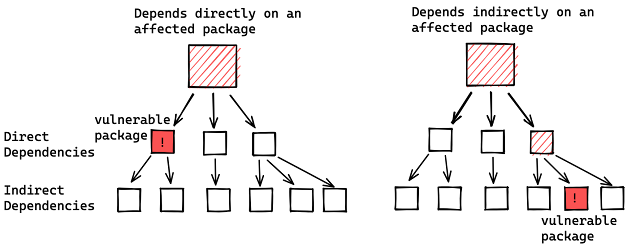
A vulnerable Log4J library can be buried under a multi-level dependency tree. If any of your libraries are using a vulnerable dependency, look for their latest fixed versions or talk to your security team.

Read More

Log4J 2.16.0 is Vulnerable to DoS. Upgrade to 2.17.0.

ALERT: Log4J 2.17.0 is vulnerable to RCE attack. Switch to 2.17.1. For more details: Log4J 2.17.0 is Vulnerable to RCE. Upgrade to 2.17.1.

Dear Java Developers, cancel your holiday plans. Another Log4j vulnerability was reported on December 16th Thursday and a new Log4j version is released with the patch on December 18th Saturday. Log4J 2.16.0 is no longer safe.

The new vulnerability independently discovered by Hideki Okamoto of Akamai Technologies, Guy Lederfein of Trend Micro Research working with Trend Micro’s Zero Day Initiative, and another anonymous vulnerability researcher allows denial of service attack on systems using Log4j 2.0-beta9 to 2.16.0. Remember that Log4j 2.16.0 was released last week to fix the CVE-2021-44228 vulnerability and chances are high for most of the Java projects already being upgraded to Log4j 2.16.0 which is vulnerable to DoS attack now.


Log4J 2.16.0 is Vulnerable. Switch to 2.17.0

Similar to the previous vulnerability, the CVE-2021-45105 doesn't mean everyone using Log4j 2.0-beta9 to 2.16.0 is vulnerable. This uncontrolled recursion from self-referential lookups bug affects only if your Log4j configuration has Context Lookups like ${ctx:loginId} or $${ctx:loginId}. Though removing such context lookups where they originate from sources external to the application such as HTTP headers or user input is one way to solve the issue, it is recommended to replace Context Lookups like ${ctx:loginId} or $${ctx:loginId} with Thread Context Map patterns (%X, %mdc, or %MDC). Instead, you can upgrade to the latest Log4j version 2.17.0.

Similar to CVE-2021-44228, CVE-2021-45105 also affects log4j-core only.

Last Friday, Google published a blog post claiming more than 35,000 Java packages in the Maven Central repository are affected by Log4j vulnerability. By the time of publishing that article only 5000 artifacts were patched. That leaves 30,000 packages hanging around with vulnerable Log4j dependency. Google also mentioned that in more than 80% of the packages, the vulnerability is more than one level deep, with a majority affected five levels down (and some as many as nine levels down). This makes fixing them hard as a package maintainer you have to rely on your dependency maintainer to publish a fixed version.

Coming to the projects you have control over, you have to go through the same cycle once more to upgrade all your Log4j dependencies to the latest version 2.17.0.

Let me repeat the process for developers to identify the vulnerable Log4J versions.

Run the following command from your project folder.

mvn dependency:tree

Any Log4J dependency with a version less than 2.17.0 is most likely vulnerable or unmaintained. Maven central repository has a new column with the number of vulnerabilities in each Log4j version.

Log4J 2.16.0 is Vulnerable to DoS. Switch to 2.17.0.

If you encounter any vulnerable Log4j versions as your direct dependencies defined in your pom file, or in your parent pom file, upgrade them immediately. Remember by defining the following dependency in your pom file, you can override the dependency defined in your parent pom file.

<dependency>
    <groupId>org.apache.logging.log4j</groupId>
    <artifactId>log4j-core</artifactId>
    <version>2.17.0</version>
</dependency>


Log4J 2.16.0 is Vulnerable. Switch to 2.17.0 
Image Credits: Google

A vulnerable Log4J library can be buried under a multi-level dependency tree. If any of your libraries are using a vulnerable dependency, look for their latest fixed versions or talk to your security team.

Read More

How to Fix Log4J Vulnerability

ALERT 1: Log4J 2.16.0 is vulnerable to DoS attack. Switch to 2.17.0. For more details: Log4J 2.16.0 is Vulnerable to DoS. Switch to 2.17.0.


ALERT 2: Log4J 2.17.0 is vulnerable to RCE attack. Switch to 2.17.1. For more details: Log4J 2.17.0 is Vulnerable to RCE. Upgrade to 2.17.1.


Log4j security vulnerability has stolen the sleep of developers over the last week. Though it is a little late, this article explains how to identify if your project is using Log4j and how to fix the problem. Let's start with the problem description: In Apache Log4j2 versions up to and including 2.14.1 (excluding security release 2.12.2), the JNDI features used in configurations, log messages, and parameters do not protect against attacker-controlled LDAP and other JNDI related endpoints. An attacker who can control log messages or log message parameters can execute arbitrary code loaded from LDAP servers when message lookup substitution is enabled.

How to fix Log4J Vulnerability


Note that only the log4j-core JAR file is impacted by this vulnerability. Applications using only the log4j-api JAR file without the log4j-core JAR file are not impacted by this vulnerability.


Though the Log4j you are using in your project is vulnerable doesn't mean that your project is vulnerable. If you are behind a firewall with no external access or if you don't log any user inputs, chances to attack your system are slim. However, it doesn't mean you can relax since it is always a best practice to fix vulnerabilities in the project regardless of whether you are affected or not.


Read More

Read Carbondata Table from Apache Hive

Apache Carbondata an indexed columnar data store heavily depends on Apache Spark but also supports other Big Data frameworks like Apache Hive and Presto. This article explains how to read a Carbondata table created in Apache Spark from Apache Hive in two sections: 1. How to create a table in HDFS using Apache Spark, 2. How to read the Carbondata table from Apache Hive.

Read Carbondata Table from Apache Hive
Requirements:
  • Oracle JDK 1.8
  • Apache Spark
  • Apache Hadoop (Carbondata officially support Hive 2.x. In this article, Apache Hadoop 2.7.7 is used)
  • Apache Hive (Carbondata officially support Hive 2.x. So better to stick to 2.x version. In this article, Apache Hive 2.3.6 is used to demonstrate the integration)
  • Carbondata libraries
Please follow the Integrate Carbondata with Apache Spark Shell article to compile Carbondata from source and integrate it with Apache Spark. This article is written based on the assumption that you have already followed all the steps from the above-mentioned article.

Read More

Integrate Carbondata with Apache Spark Shell

Apache Carbondata an indexed columnar data store solution for fast analytics on big data platform, e.g.Apache Hadoop, Apache Spark, etc. This article is written to provide a quick start guide on how to integrate Carbondata with Apache Spark Shell. Why another article while there is a quick start guide on the official website? Things are not always as smooth as expected. In my experience, integrating Carbondata with Apache Spark using pre-built binaries didn't work as expected. So here is the quick start tutorial.

Integrate Carbondata with Apache Spark Shell
Requirements:
Carbondata requires Java 1.7 or 1.8 to run and Apache Maven to build from source. Please make sure that you have Oracle JDK 1.8, supporting Apache Maven and Git to setup Carbondata. If you don't have Oracle JDK or Apache Maven installed in your system, please follow the given links below to install them first.

Read More

Apache Maven for Beginners

Apache Maven is a build tool widely being used by Java developers to manage project dependencies, control build process and automate tests. Apache Maven makes our life easier especially in building a complex Java project. However, beginners stay away from Apache Maven as I did years ago just because they find it complex to learn and use. This article simplifies the concept of Apache Maven and introduces Maven in a smooth way to beginners. In this article, you will see how you can use Apache Maven to manage your project dependencies using a simple Java project as an example. The article is structured into two main topics: Apache Maven in Eclipse and Apache Maven in IntelliJ IDEA. Of course, you can use Apache Maven without any IDEs. However, I stick with IDEs to make it simple for beginners. Other applications of Apache Maven like build management and test automation will be covered in another article.
Let's begin with manual dependency management using a simple calculator application. Suppose you want to develop a Calculator that receives a simple arithmetic expression like "2 + 3 * 5" as input and prints the output in the console. It is a complex task to evaluate such a String input and calculate the result by ourselves. Fortunately, there is a library: exp4j which can evaluate a String expression and return the output.
Read More

Spark 05: List Action Movies with Spark flatMap

Welcome to the fifth article in the series of Apache Spark tutorials. In this article, you will learn the application of flatMap transform operation. After the introduction to flatMap operation, a sample Spark application is developed to list all action movies from the MovieLens dataset.

Spark 05: List Action Movies with Spark flatMap

In the previous articles, we have used the map transform operation which transforms an entity into another entity where the transformation is one-to-one. For example, suppose you have a String RDD named lines, applying lines.map(x => x.toUpperCase) operation creates a new String RDD with the same number of records but with uppercase string literals as shown below:
Read More

Spark 04: Key-Value RDD and Average Movie Ratings

In the first article of this series: Spark 01: Movie Rating Counter, we created three RDDs (data, filteredData and ratingData) each contains a singular datatype. For example, data and filteredData were String RDDs and the ratingRDD was a Float RDD. However, it is common to use an RDD which can store complex datatypes especially Key-Value pairs depending on the requirement. In this article, we will use a Key-Value RDD to calculate the average rating of each movie in our MoviLens dataset.  Those who don't have the MovieLens dataset, please visit the Spark 01: Movie Rating Counter article to setup your environment.

Spark 04: Key Value RDD and Average Movie Ratings

As you already know, the ratings.csv file has the fields movieId and rating. A given movie may get different ratings from different users. To get the average ratings of each movie, we need to add all ratings of each movie individually and divide the sum by the number of ratings.

Read More

Spark 03: Understanding Resilient Distributed Dataset

You are not qualified as an Apache Spark developer until you know what is a Resilient Distributed Dataset (RDD). It is the fundamental technique to represent data in the Spark memory. There are advanced data representation techniques like DataFrame built on top of RDD. However, it is always better to start with the most basic dataset: RDD. RDD is nothing other than a data structure with some special properties or features.

Spark 03: Understanding Resilient Distributed Dataset

We all know that Apache Spark is a distributed general-purpose cluster-computing framework. There are some common problems faced in a distributed environment including but not limited to:
  1. Remote access of data is expensive
  2. High chance of failure
  3. Runtime errors are expensive and hard to track
  4. Wasting computing power is way too expensive
RDD is designed to address the abovementioned problems. In the following section, you will see the properties of RDD and how it solves these problems.
Read More

Spark 01: Movie Rating Counter

Apache Spark is a must to know framework for big data developers. This is an attempt to write a series of articles on Apache Spark to train you from zero to hero. In this series of articles, I will use the latest Apache Spark release which is 2.4.0 as of 2019 January. In the first few articles, we will code and test Apache Spark on IntelliJ Idea. As you may already know, Apache Spark is developed using Scala and of course, there are APIs available for other languages including Java and Python. Still, Scala has preferred over other languages for its performance and compact code. Therefore, you need to prepare the environment first.

Spark 01: Movie Rating Counter

My articles will be based on Frank Kane's course on Udemy: Apache Spark 2 with Scala - Hands On with Big Data! I highly recommend his tutorial if you prefer for a video tutorial.

Setup the Environment

Apache Spark 2.4.0 depends on Scala 2.12 which in turn depends on Java 1.8. Scala is unlike Java not very version compatible language. Therefore, please take special care on choosing versions.

Step 1:
Install Oracle Java Development Kit 1.8 on your system. Linux users can follow this article: Install Oracle JDK 8 on Linux

Step 2:
Install the latest IntelliJ IDEA. Again, Linux users can follow my article: Install IntelliJ IDEA on Linux

Step 3:
Install Scala plugin in IntelliJ IDEA. Regardless of your operating system, you can follow the article Setup Scala on IntelliJ IDEA.

Read More
Install Apache Maven on Linux

Install Apache Maven on Linux

Ubuntu and most other Linux distributions have Apache Maven in their official repository but I prefer manual installation to avoid dependencies like Open JDK. This article explains how you can install the latest Apache Maven in Linux.


Requirements:
Apache Maven depends on Java Development Kit so you must have either Oracle JDK or OpenJDK installed on your system. In case if you do not have JDK in your system, follow these articles first and install Oracle JDK on your computer.

Read More

Apache Thrift Client for WSO2 CEP

In the series of WSO2 CEP tutorials, this article explains how to create Apache Thrift publisher and receiver for a CEP server in Python. Even though this is javahelps.com, I use Python since publisher and receiver in Java are already available in WSO2 CEP samples. 
One of the major advantages of Apache Thrift is the support for various platforms. Therefore this tutorial can be simply adapted to any other languages with less effort.

WSO2 CEP supports various protocols as a server to send and receive events. However using TCP protocol is recommended when the performance is a critical requirement. To achieve the security without performance trade-off, an SSL connection is used to authenticate the connection and the actuals events are be sent to the interested parties through unencrypted TCP connections.

Apache Thrift Client for WSO2 CEP

Requirements:
  • Apache Thrift
  • Python 2
  • Java Development Kit 1.7 or Latest
  • WSO2 Complex Event Processor 4.2.0

Setting up the environment
Step 1:
If you don't have Apache Thrift compiler, install it using the following command. Windows and Mac users, please find the binary files here.
sudo apt install thrift-compiler

Install the Python thrift library using the following command. Windows and Mac users must install this library using pip or manually include the library into the project.
sudo apt install python-thrift

Step 2:
Download and extract the WSO2 CEP pack. Start the server using the following command.
sh <CEP_HOME>/bin/wso2server.sh

Step 3:
Create a new stream using the following properties.
Event Stream Name com.javahelps.stream.Temperature
Payload data attributes
  • location STRING
  • temp INT

Step 4:
Create a publisher for testing purposes using the following configurations:
Event Publisher Name com.javahelps.publisher.logger.Temperature
Event Source com.javahelps.stream.Temperature
Output Event Adapter Type logger
Message Format text
Apache Thrift Client for WSO2 CEP
Now we have the required platform and let's jump into coding.

Step 1:
Create a new workspace directory wherever you like. Create a child directory wso2-thrift inside it and download the following files into the wso2-thrift directory from WSO2 GitHub repository.
  • Data.thrift
  • Exception.thrift
  • ThriftEventTransmissionService.thrift
  • ThriftSecureEventTransmissionService.thrift
Step 2:
Open the terminal inside the parent directory and execute the following commands to generate Python source files.
thrift -r --gen py wso2-thrift/Data.thrift
thrift -r --gen py wso2-thrift/Exception.thrift
thrift -r --gen py wso2-thrift/ThriftEventTransmissionService.thrift
thrift -r --gen py wso2-thrift/ThriftSecureEventTransmissionService.thrift
After executing these commands, you will get a gen-py directory which contains the generated source files.

Step 3:
The thrift receiver will run as a server and which requires an SSL certificate. Create the certificate using the following command. You need to answer the questions asked by openssl during this process.
openssl req -x509 -nodes -days 365 -newkey rsa:2048 -keyout server.key -out server.crt

For example:
Country Name (2 letter code) [AU] CA
State or Province Name (full name) [Some-State] Ontario
Locality Name (eg, city) [] London
Organization Name (eg, company) [Internet Widgits Pty Ltd] Western University
Organizational Unit Name (eg, section) []: Faculty Of Engineering
Common Name (e.g. server FQDN or YOUR name) [] Gobinath
Email Address [] admin@javahelps.com


Step 5:
Once you have created the server.crt and server.key files, combine them into server.pem file using the following command.
cat server.crt server.key > server.pem

Step 6:
To register our SSL server as a reliable client to the CEP, enter the following command and restart the CEP.
keytool -importcert -file server.crt -keystore <CEP_HOME>/repository/resources/security/client-truststore.jks -alias "PythonThriftClient"

In the above command, the alias  PythonThriftClient can be anything and the <CEP_HOME> must be replaced by the actual home directory of WSO2 CEP.

When prompted, enter the keystore password 'wso2carbon' and confirm to trust the certificate.

Step 7:
Create a new file ServerHandler.py with the following code:
#!/usr/bin/env python


class ServerHandler(object):
    """
        ServerHandler contains the functions to serve the requests from WSO2 CEP.
    """
    def __init__(self):
        pass

    """
        Receive the username and password, verify it and return a unique session id.
    """
    def connect(self, uname, password):
        print 'Connect ' + uname + ':' + password
        return '123456'  # A random session id

    """
        Destroy the session.
    """
    def disconnect(self, sessionId):
        print 'Disconnect the session ' + str(sessionId)

    def defineStream(self, sessionId, streamDefinition):
        return ''

    def findStreamId(self, sessionId, streamName, streamVersion):
        return ''

    """
        Receive the event and process it.
    """
    def publish(self, eventBundle):
        print 'Received a new event: ' + str(eventBundle) + '\n'

    def deleteStreamById(self, sessionId, streamId):
        pass

    def deleteStreamByNameVersion(self, sessionId, streamName, streamVersion):
        pass

Step 8:
Create a new file TCPServer.py with the following code:
#!/usr/bin/env python

import sys
sys.path.append('gen-py')
from thrift.transport import TSocket
from thrift.transport import TTransport
from thrift.protocol import TBinaryProtocol
from thrift.server import TServer
from ServerHandler import ServerHandler
from ThriftEventTransmissionService import ThriftEventTransmissionService

SERVER_ADDRESS = 'localhost'
SERVER_PORT = 8888

handler = ServerHandler()
processor = ThriftEventTransmissionService.Processor(handler)
transport = TSocket.TServerSocket(SERVER_ADDRESS, SERVER_PORT)
tfactory = TTransport.TBufferedTransportFactory()
pfactory = TBinaryProtocol.TBinaryProtocolFactory()

server = TServer.TSimpleServer(processor, transport, tfactory, pfactory)

print 'Starting TCP Server at ' + SERVER_ADDRESS + ':' + str(SERVER_PORT)

server.serve()

Note the server port is 8888

Step 9:
Create a new file SSLServer.py with the following code:
#!/usr/bin/env python

import sys
import os
sys.path.append('gen-py')
from thrift.transport import TTransport
from thrift.protocol import TBinaryProtocol
from thrift.server import TServer
from thrift.transport import TSSLSocket
from ServerHandler import ServerHandler
from ThriftSecureEventTransmissionService import ThriftSecureEventTransmissionService


SERVER_ADDRESS = 'localhost'
SERVER_PORT = 8988
CERTIFICATE_FILE = os.path.join(os.path.dirname(os.path.realpath(__file__)), 'server.pem')

handler = ServerHandler()
processor = ThriftSecureEventTransmissionService.Processor(handler)
transport = TSSLSocket.TSSLServerSocket(SERVER_ADDRESS, SERVER_PORT, certfile=CERTIFICATE_FILE)
tfactory = TTransport.TBufferedTransportFactory()
pfactory = TBinaryProtocol.TBinaryProtocolFactory()

server = TServer.TSimpleServer(processor, transport, tfactory, pfactory)

print 'Starting SSL Server at ' + SERVER_ADDRESS + ':' + str(SERVER_PORT)

server.serve()

Note the server port is 8988

Step 10:
Create a new file Publisher.py with the following code:
#!/usr/bin/env python

import sys
import time
sys.path.append('gen-py')

from ThriftSecureEventTransmissionService import ThriftSecureEventTransmissionService
from ThriftEventTransmissionService import ThriftEventTransmissionService
from ThriftEventTransmissionService.ttypes import *

from thrift import Thrift
from thrift.transport import TSSLSocket
from thrift.transport import TSocket
from thrift.transport import TTransport
from thrift.protocol import TBinaryProtocol


class Publisher:

    """
        Create SSL and TCP sockets along with buffer and binary protocol.
    """
    def __init__(self, ip, ssl_port, tcp_port):
        # Make SSL socket
        self.ssl_socket = TSSLSocket.TSSLSocket(ip, ssl_port, False)
        self.ssl_transport = TTransport.TBufferedTransport(self.ssl_socket)
        self.ssl_protocol = TBinaryProtocol.TBinaryProtocol(self.ssl_transport)

        # Make TCP socket
        self.tcp_socket = TSocket.TSocket(ip, tcp_port)
        self.tcp_transport = TTransport.TBufferedTransport(self.tcp_socket)
        self.tcp_protocol = TBinaryProtocol.TBinaryProtocol(self.tcp_transport)

    def connect(self, username, password):
        # Create a client to use the protocol encoder
        self.ssl_client = ThriftSecureEventTransmissionService.Client(self.ssl_protocol)
        self.tcp_client = ThriftEventTransmissionService.Client(self.tcp_protocol)

        # Make connection
        self.ssl_socket.open()
        # self.transport.open()
        self.sessionId = self.ssl_client.connect(username, password)

        self.tcp_socket.open()

    def defineStream(self, streamDef):
        # Create Stream Definition
        return self.tcp_client.defineStream(self.sessionId, streamDef)

    def publish(self, streamId, *attributes):
        # Build thrift event bundle
        event = EventBundle()
        event.setSessionId(self.sessionId)
        event.setEventNum(1)
        event.addLongAttribute(time.time() * 1000)
        event.addStringAttribute(streamId)
        for attr in attributes:
            if isinstance(attr, int):
                event.addIntAttribute(attr)
            elif isinstance(attr, basestring):
                event.addStringAttribute(attr)
            elif isinstance(attr, long):
                event.addLongAttribute(attr)
            elif isinstance(attr, float):
                event.addDoubleAttribute(attr)
            elif isinstance(attr, bool):
                event.addBoolAttribute(attr)
            else:
                event.setArbitraryDataMapMap(attr)

        # Publish
        self.tcp_client.publish(event.getEventBundle())

    def disconnect(self):
        # Disconnect
        self.ssl_client.disconnect(self.sessionId)
        self.ssl_transport.close()
        self.ssl_socket.close()

        self.tcp_transport.close()
        self.tcp_socket.close()


class EventBundle:
    __sessionId = ""
    __eventNum = 0
    __intAttributeList = []
    __longAttributeList = []
    __doubleAttributeList = []
    __boolAttributeList = []
    __stringAttributeList = []
    __arbitraryDataMapMap = None

    def setSessionId(self, sessionId):
        self.__sessionId = sessionId

    def setEventNum(self, num):
        self.__eventNum = num

    def addIntAttribute(self, attr):
        self.__intAttributeList.append(attr)

    def addLongAttribute(self, attr):
        self.__longAttributeList.append(attr)

    def addDoubleAttribute(self, attr):
        self.__doubleAttributeList.append(attr)

    def addBoolAttribute(self, attr):
        self.__boolAttributeList.append(attr)

    def addStringAttribute(self, attr):
        self.__stringAttributeList.append(attr)

    def setArbitraryDataMapMap(self, attr):
        self.__arbitraryDataMapMap = attr

    def getEventBundle(self):
        return Data.ttypes.ThriftEventBundle(self.__sessionId, self.__eventNum, self.__intAttributeList, self.__longAttributeList, self.__doubleAttributeList, self.__boolAttributeList, self.__stringAttributeList, self.__arbitraryDataMapMap)

Step 11:
Create a new file PublisherClient.py with the following code:
#!/usr/bin/env python

from Publisher import Publisher

CEP_SERVER_ADDRESS = '192.168.122.1' # IP address of the server. You can find it at the end of the CEP console
SSL_PORT = 7711  # Thrift SSL port of the server
TCP_PORT = 7611     # Thrift TCP port of the server
USERNAME = 'admin' # Username
PASSWORD = 'admin'  # Passowrd

publisher = Publisher(CEP_SERVER_ADDRESS, SSL_PORT, TCP_PORT)

# Connect to server with username and password
publisher.connect(USERNAME, PASSWORD)

# Publish an event to the Temperature stream
publisher.publish('com.javahelps.stream.Temperature:1.0.0', 'Kitchen', 56)

# Disconnect
publisher.disconnect()
Change the CEP_SERVER_ADDRESS according to your system. The SSL_PORT and TCP_PORT of the CEP must be as given default values. If they differ, we will update them in Step 15.

See the complete directory structure below:
.
├── gen-py
│   ├── Data
│   │   ├── constants.py
│   │   ├── __init__.py
│   │   ├── __init__.pyc
│   │   ├── ttypes.py
│   │   └── ttypes.pyc
│   ├── Exception
│   │   ├── constants.py
│   │   ├── __init__.py
│   │   ├── __init__.pyc
│   │   ├── ttypes.py
│   │   └── ttypes.pyc
│   ├── __init__.py
│   ├── ThriftEventTransmissionService
│   │   ├── constants.py
│   │   ├── __init__.py
│   │   ├── __init__.pyc
│   │   ├── ThriftEventTransmissionService.py
│   │   ├── ThriftEventTransmissionService.pyc
│   │   ├── ThriftEventTransmissionService-remote
│   │   ├── ttypes.py
│   │   └── ttypes.pyc
│   └── ThriftSecureEventTransmissionService
│       ├── constants.py
│       ├── __init__.py
│       ├── __init__.pyc
│       ├── ThriftSecureEventTransmissionService.py
│       ├── ThriftSecureEventTransmissionService.pyc
│       ├── ThriftSecureEventTransmissionService-remote
│       ├── ttypes.py
│       └── ttypes.pyc
├── PublisherClient.py
├── Publisher.py
├── server.crt
├── ServerHandler.py
├── server.key
├── server.pem
├── SSLServer.py
├── TCPServer.py
└── wso2-thrift
    ├── Data.thrift
    ├── Exception.thrift
    ├── ThriftEventTransmissionService.thrift
    └── ThriftSecureEventTransmissionService.thrift

Step 12:
Go to the CEP dashboard and create a new WSO2 event receiver. As shown below.
Event Receiver Name com.javahelps.receiver.Temperature
Input Event Adapter Type wso2event
Event Stream com.javahelps.stream.Temperature:1.0.0
Message Format wso2event
Apache Thrift Client for WSO2 CEP

Compare the ports available for Thrift protocol with the SSL_PORT and TCP_PORT in  PublisherClient.py . If there are any differences, update the  SSL_PORT and TCP_PORT values.

Step 13:
Add another publisher to publish the events to our Python servers. Use the following configuration.
Event Publisher Name com.javahelps.publisher.thrift.Temperature
Event Source com.javahelps.stream.Temperature
Output Event Adapter Type wso2event
Receiver URL tcp://localhost:8888
Authenticator URL ssl://localhost:8988
Username admin (Can be anything. Our authenticator accepts any username)
Password admin (Can be anything. Our authenticator accepts any password)
Protocol thrift
Publishing Mode non-blocking
Publishing Timeout 0
Message Format wso2event
Apache Thrift Client for WSO2 CEP

Step 14:
Start the TCPServer.py and SSLSErver.py using the following commands.
python TCPServer.py
python SSLSErver.py

Step 15:
Send an event to the WSO2 CEP server from PublisherClient using the following command and see the results in terminal.
python  PublisherClient.py

Apache Thrift Client for WSO2 CEP

Now we have successfully created a Thrift event publisher and receiver to send and receive events to and from WSO2 Complex Event Processor. To implement such a client in a different language, you need to change the Python related steps only. The Python clients along with the CEP artifacts are available at the following GitHub repository.

Find the project @ GitHub.
Read More

Set Proxy for Maven in Eclipse

If your computer connects with Internet through a proxy server, Maven plugin of Eclipse will not update the project artifacts or Maven plugins. The system proxy settings or proxy settings of Eclipse are not detected by Maven plugin. This tutorial shows you the way to enable proxy for Maven in Eclipse. If you want to configure the proxy for the Apache Maven command line tool, follow the steps 1 and 2 only.

Step 1:
Copy and paste the following content in your favorite editor and save it as settings.xml in the given directory.
<?xml version="1.0" encoding="UTF-8"?>
<settings
 xmlns="http://maven.apache.org/SETTINGS/1.0.0" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
 xsi:schemaLocation="http://maven.apache.org/SETTINGS/1.0.0 http://maven.apache.org/xsd/settings-1.0.0.xsd">
 <pluginGroups/>
 <proxies>
  <!-- Proxy for HTTP -->
  <proxy>
   <id>optional</id>
   <active>true</active>
   <protocol>http</protocol>
   <username>proxyuser</username>
   <password>proxypass</password>
   <host>proxy.host.net</host>
   <port>80</port>
   <nonProxyHosts>local.net</nonProxyHosts>
  </proxy>

  <!-- Proxy for HTTPS -->
  <proxy>
   <id>optional</id>
   <active>true</active>
   <protocol>https</protocol>
   <username>proxyuser</username>
   <password>proxypass</password>
   <host>proxy.host.net</host>
   <port>80</port>
   <nonProxyHosts>local.net</nonProxyHosts>
  </proxy>
 </proxies>

 <servers/>
 <mirrors/>
 <profiles/>
</settings>
Directory for Linux users:
/home/{username}/.m2/
Read More

Install Apache Tomcat on Ubuntu

Ubuntu repository does not provide the latest version of Apache Tomcat. If you are desired to install the latest version of Apache Tomcat and to add it to the Eclipse, this article is for you.


Requirements:
ApacheTomcat depends on Java Development Kit so you must have either Oracle JDK or OpenJDK installed on your system. In case if you do not have JDK in your system, follow these articles first and install Oracle JDK on your computer.

Read More

Contact Form

Name

Email *

Message *